AI agents need an owned memory layer before scaling
 Reviewed by Helen Jones
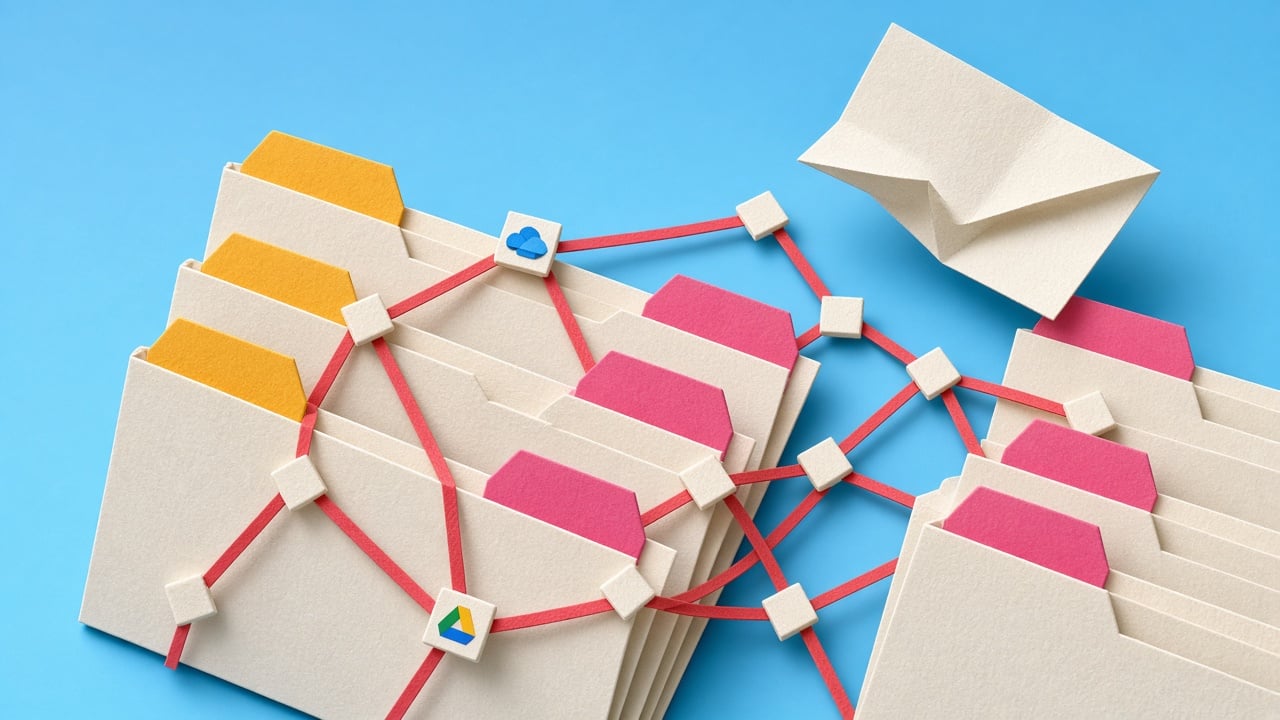
OpenAI published a 21 September case study of V7 Go, a platform that turns company files into a source-linked Context Graph for agent workflows. V7 says the graph connects entities, relationships and evidence from repositories such as SharePoint and Google Drive, so workflows can retrieve context instead of rediscovering it in every run.
Most teams notice the same failure before they call it a memory problem: each new AI task starts with another paste-in, another search, and another debate about which file is current. Chat history and a long prompt can help for one interaction, but neither establishes which sources, terms, and rules the next person or workflow should trust. That makes shared context an operating decision, not a model setting. The useful lesson from V7 is the design pattern—named source systems, traceable evidence, a process for updating records, and a boundary for what an agent may retrieve—not its reported performance figures or a promise that every team needs a graph.
Analysis
Choose one recurring AI-assisted workflow and list its authoritative files, business terms, owner, and update trigger. If the list is unclear, fix that context pack before adding another agent or expanding access.
Source note
Pulse published by Collab365 Spaces, reviewed by Helen Jones on . Cite as "AI agents need an owned memory layer before they scale", Collab365 Spaces.